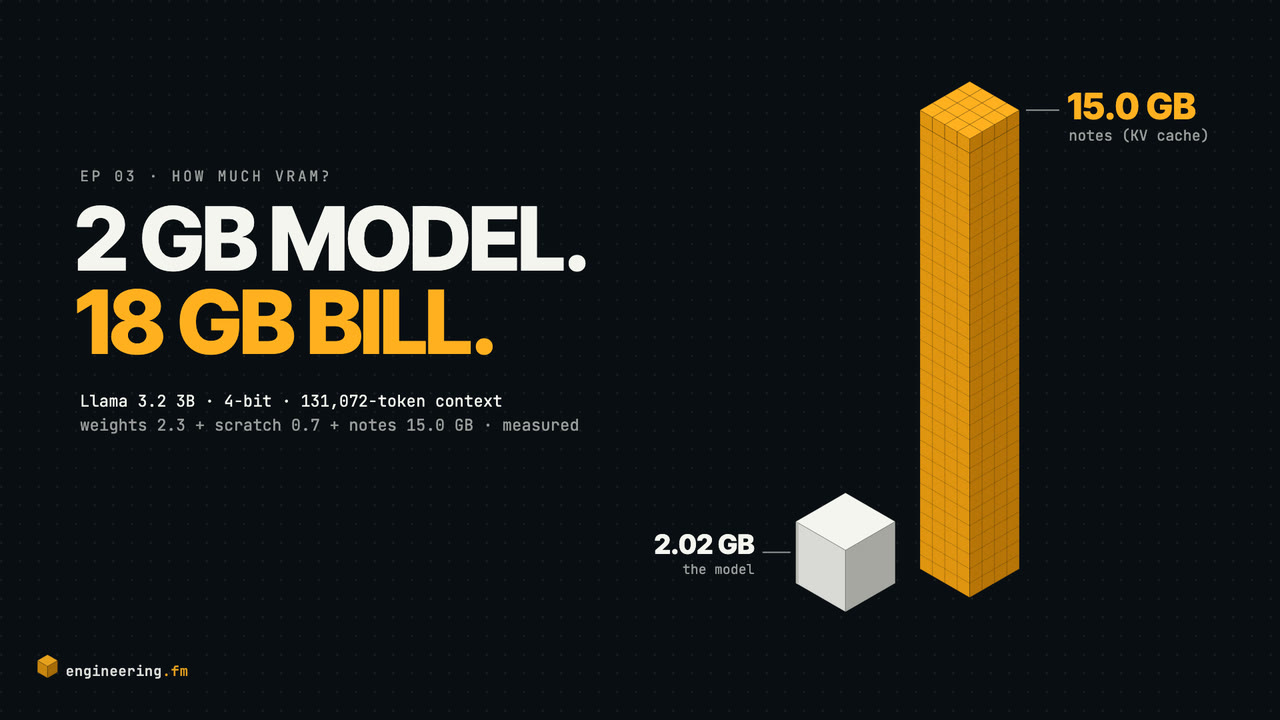
How much VRAM you need to run an LLM locally
Where every gigabyte goes when you run a language model on your own machine: the weights, the KV cache, and what spills over.
Signature animationOne token's KV-cache notes stacking into a tower that dwarfs the 2 GB model and overflows the card